Model Hub routes your own models to your Agents on your machine. It is separate from Model Service, which supplies cloud models for Avibe features such as Voice input.
- Providers & routing configures where models come from and how each Agent reaches them.
- Tools shows the tools Vibey can call, including web search and local-first web fetch, and what real use showed about them. See Use hosted tools.
- Usage shows calls metered by Model Hub. See Explore usage.
- Subscription quota shows the limits of each subscription added as a Model Hub provider and what its use is worth at API prices. See Check subscription quota.
- Providers lists the subscriptions, model API keys, and search/fetch services you own. It is an inventory, not a priority list; a service-only provider supplies no models.
- Routes shows each Agent backend and the effective Route chain for each model, inherited from default routing or saved as a manual override.
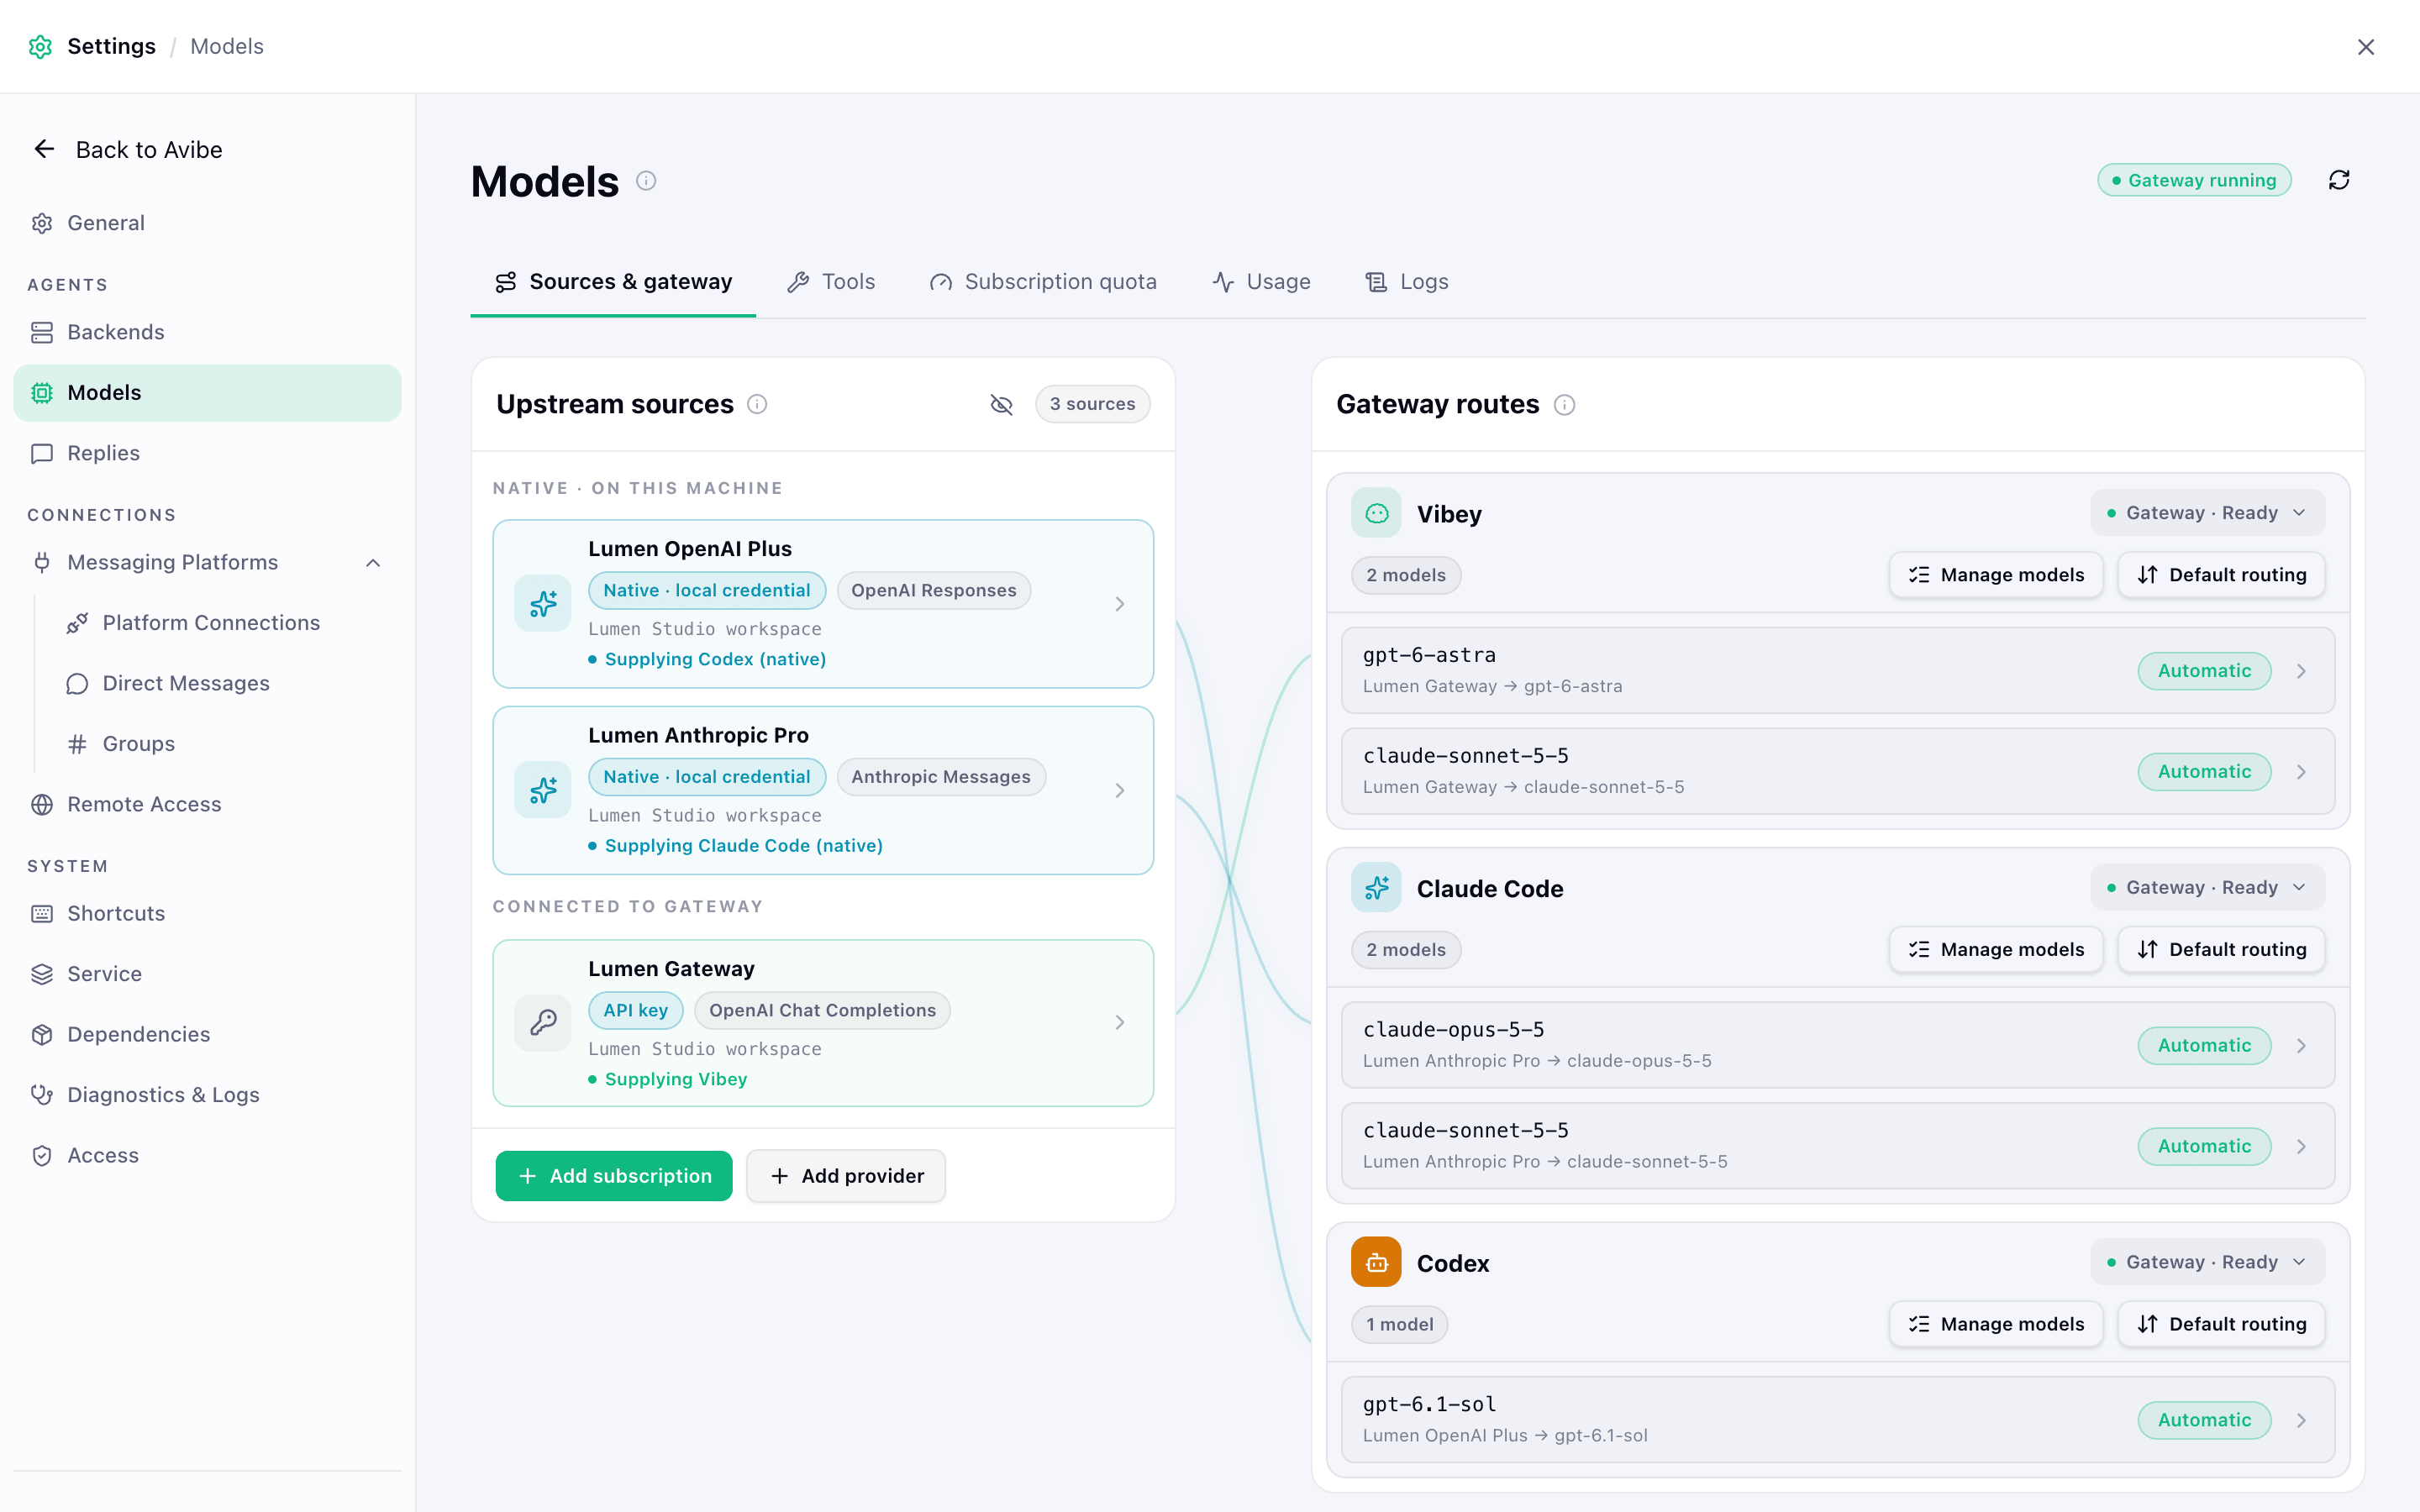
Product UI, sample project data.
Choose who manages a backend
Each Agent backend is either Managed by Model Hub (shown as Managed) or uses its Own login, the CLI’s own native configuration. Managed is the default on a fresh installation. An existing installation with no Model Hub configuration keeps every backend on its own login, and the Models page says All N backends use their own login, until you select Let Model Hub manage for a backend. For Claude Code, Codex, and OpenCode, the choice is per backend and reversible. Selecting Use own login keeps your providers and Route chains, but that backend resumes using its own native configuration. An Own login hop inside a Route chain still leaves the backend managed by Model Hub: Avibe owns fallback and recovery for that chain. Vibey, Avibe’s built-in agent, has no own-login option: it reaches models only through Model Hub, from providers Model Hub holds. While Vibey has models, Model Hub cannot be turned off; remove Vibey’s models first.Migrate saved API keys
Select Migrate configuration on the Models page to import supported keys from native CLI configuration files, shell startup files, or credential stores. Migration copies the saved key, Base URL, interface and configured model entries. It does not test the key online or fetch a model list before saving it, so an expired key or an unavailable provider does not block the other keys from being imported. Newly imported API-key providers appear as Saved, not as verified connections. Later model requests establish whether they work and report any provider error through Model Hub. API keys stay in their original configuration by default. Select the cleanup option only if you also want the migrated keys removed from the native configuration. If you may switch the backend back to Own login, keep the native keys or reconfigure them before switching; cleanup can remove the only credential that backend can use on its own login. Local file-format, credential-access and concurrent-change checks still apply. Subscription sign-ins use a separate credential-ownership transfer; they are not copied like static API keys.Add a provider
Add a subscription
- In Providers, select Add subscription and choose the provider.
- For Claude, choose who holds the sign-in. Add as a Model Hub provider is selected by default; Use own login is the other option.
- Select Sign in and complete the provider’s sign-in flow.
- Claude: with Use own login, Claude Code keeps using its local login instead, and that subscription supplies only Claude Code. Anthropic’s subscription terms cover only its own apps, such as Claude Code and claude.ai; Avibe shows this as one line under the Claude option. Read Anthropic’s terms before you add a Claude subscription to Model Hub.
- ChatGPT and the other subscriptions are added to Model Hub only. Native Codex sign-in remains supported when Codex is already signed in, but quota exhaustion will not trigger Model Hub takeover and its usage stays outside Model Hub.
Add an API key
For a model provider, follow these steps. To add Tavily, Exa, or DeepSeek for web search or web fetch, use Add a search service.- Select Add API key.
- Choose a Provider. Picking DeepSeek, Qwen, Kimi, and the like fills in the official address and API format; for anything else, choose Other provider · enter its address. Then enter an optional name, the Base URL, and the API key. A custom Base URL can point to a relay, aggregator, or self-hosted compatible service.
- Select Add. Avibe connects once, authenticates, identifies the interface, and fetches the model list before saving.
Maintain the model list
After a model-supplying provider is added, Avibe opens Provider details > Models. Service-only providers have no model list. For a model provider, you can:- Select Refetch to test the saved provider, update its health, and refresh discovered models. This is the only saved-provider refresh action.
- Select Add model ID to add a model manually when discovery cannot find it.
- Edit the exact reasoning tiers accepted by any discovered or manual model. No tier is selected or filled by default.
- Remove models you added manually. Models reported by the provider are managed by refetch instead.
Configure default routing
In Routes, choose a backend and open Default routing to select its default providers and arrange their order. Models without a nonempty saved manual override follow these defaults; an empty saved chain also inherits them. Each effective Route chain is an ordered list of exact pairs: a provider and the upstream model it should call. For example, suppose two API-key providers have the default order A, then B, and you requestmodel-x. If only B lists model-x, the chain contains only B. If neither provider lists it, the chain is A, then B, using model-x unchanged at each hop. It does not try an unmatched A before a known match on B.
Avibe first includes all eligible matches in default order, including matching subscriptions. Only when there are no matches does it use eligible default API-key providers with the requested model ID unchanged. Subscriptions are not candidates for unknown-model passthrough. Native Claude matching recognizes its supported aliases and versions. For Claude Code on other providers, the family aliases (fable, opus, opus[1m], sonnet, sonnet[1m], and haiku) resolve to the newest matching full ID listed by each provider, skipping retired models; a provider that lists no full ID for the family gives the alias nothing to resolve to, so select a full ID there. Other API model selections and other backends remain exact-ID matches. Temporary unavailability does not turn a matched chain into passthrough.
New models follow defaults automatically. Changes to default membership, order, or matching evidence update inherited routes; they leave saved manual chains unchanged. The dialog shows how many models inherit defaults and how many have saved overrides. Changes apply only to the selected backend.
Select Save once to apply the default membership and order, including changes to inherited routes; there is no second affected-routes confirmation. Avibe still checks the exact impact with the server. If that impact changes while saving, the save stops and keeps your draft for retry. Removing a provider from defaults keeps manual routes that use it; deleting the provider itself removes its references through a separate guarded change.
Manage a backend’s model list
The models a backend managed by Model Hub offers come from its model list in Model Hub. The order of that list is the order the Agent sees in its model pickers. On Models > Providers & routing, each backend’s model list ends with a full-width Add model button, shown on an empty list too. A model added there is saved at once. Use Manage models in the card header to reorder, edit, and remove models. Inside Manage models, an added model goes into that dialog’s draft and is saved with its Save. When the dialog’s own search finds nothing, it offers Search providers and the model catalog for “x”, which opens the add dialog with that query.Add a model
The add dialog lists the models your providers offer. As you type, it also searches the model catalog (models.dev):- A catalog model that no provider lists appears under Model catalog, marked Not listed by a provider. Selecting it adds the model with the catalog’s details: the vendor’s own model ID (for example
claude-fable-5-2), context and output limits, input types, and reasoning efforts. No form opens. Avibe does not check that one of your providers serves it; if none does, the chat says so when the model is used. - If neither your providers nor the catalog has the model, Add “x” as a custom model adds exactly the ID you typed, with default settings and no form.
- Add custom model… opens the full editor, for an ID with settings of your own.
Add from a model picker
In Avibe’s Web interface, every model list for a managed backend ends with Add model: the chat composer, the new-session composer, project settings, channel and DM routing, the Agents page, and the New Agent dialog. It opens the add dialog in place. The added model is saved at once and selected, and you stay where you were, including an unsent message or a partly filled New Agent form.- Add model appears only for a backend managed by Model Hub, and only for the instance Owner, who is the only person who can change Model Hub. A backend on its own login lists its own native models.
- If adding fails, a notice says so and the dialog keeps your choices on screen.
Use fast mode
Some GPT and Claude models can run on their vendor’s fast tier: the same model with faster output, at a higher price. In the chat composer and the new-session composer, the model menu shows Fast next to the reasoning effort. Turn it on or off at any time. Hover over Fast to see what it does. While a chat runs fast, a small bolt appears next to the menu’s arrow.- Fast is offered when Model Hub serves the model through an API key or subscription that speaks the model’s own protocol: an OpenAI or Anthropic API key, on the official endpoint or a relay, or a ChatGPT or Claude subscription that Model Hub holds. It is not offered for an Agent on its own login or for OpenCode.
- Each reply reports whether it actually ran fast. A relay may drop the request or serve standard speed. When a fast reply is not confirmed, the bolt next to the menu’s arrow turns hollow, and a note under the reasoning effort says so. Fast stays on, and you can still turn it on or off. The next fast reply is checked again, and the bolt fills in once the provider confirms it. Usage counts only confirmed fast replies at the fast price.
- If you switch to a model without a fast tier, your choice is kept but the chat runs at standard speed. When you switch back, it runs fast again.
- A new chat in the Web interface starts with your last choice. Chats started from a chat app, scheduled tasks, and
vibe agent runuse standard speed. - If the provider refuses fast mode, for example on a Claude subscription without usage credits, the reply runs at standard speed instead of failing.
- Fast mode costs more. OpenAI and Anthropic bill it at their own higher rates, a ChatGPT plan uses more of its quota, and a Claude plan pays for it from usage credits. Check your provider’s pricing.
Edit a model route
Open a model in Routes to inspect its chain. For an inherited route, select Edit route to start a manual draft. You can:- add or remove a hop;
- reorder hops;
- change a hop’s explicit upstream model mapping, including an exact ID absent from an API-key provider’s model list; and
- select Save to store a nonempty chain as a manual override.
On upgrade, empty routes saved by earlier versions follow current defaults, including those Avibe originally generated. Nonempty routes keep their exact hops and order as manual overrides, even if originally generated, identical to the automatic result, or using models no longer listed. Retaining a stale subscription hop does not bypass subscription model checks. Use Restore automatic to make a nonempty override follow current defaults.
Restore automatic routing
In the route dialog footer, select Restore automatic to preview the inherited chain. Removing the last hop from a manual draft opens the same restore preview. This changes only the draft, and the result may be Passthrough or Unconfigured. Undo restore brings back the preceding manual draft. On Save, Avibe checks the effective route’s impact and asks you to confirm if needed before removing the override and applying inherited routing. The saved route stays unchanged until saving succeeds. Cancel or closing the dialog writes nothing. If saving fails, the draft stays available to retry.Read the status
Each model’s route badge explains where its chain comes from:
Hover over or focus a badge for its explanation, or tap it on touch devices without opening the route dialog. Escape or interaction outside the help dismisses it. These badges describe routing, not provider health or a guarantee that the upstream accepts the model; stopping Model Hub does not change the route’s origin.
If inheritance produces no eligible hops, the model shows Unconfigured. This includes an unmatched model whose defaults contain only subscriptions. Use Configure default routing to choose eligible default providers, or save a nonempty manual route. Health changes and request errors do not change the route’s origin.
Model-supplying provider rows use these states. Search services have their own
status and recovery actions.
Saved uses neutral styling. Its connection hint explains the status; it does not ask you to repair anything. A successful model request updates pending verification. For a search-capable provider, an authenticated search outcome or a conclusive free credential check can also update it. Actual cooldown, credential, or error states take priority over Saved.
Each backend card shows who manages it. A backend on its own login reads Own login. A managed backend adds a route status for the models in its list, such as Managed · Ready:
Taken over appears only when a recoverably unavailable first hop has handed the request to a later hop. A successful takeover is silent in the conversation. The Models page shows the current provider, the paused path, and the temporary replacement; the next turn returns to the first hop after it recovers, without changing your saved order.
Explore usage
Open Models > Usage to see calls metered by Model Hub. The trend appears above the details table.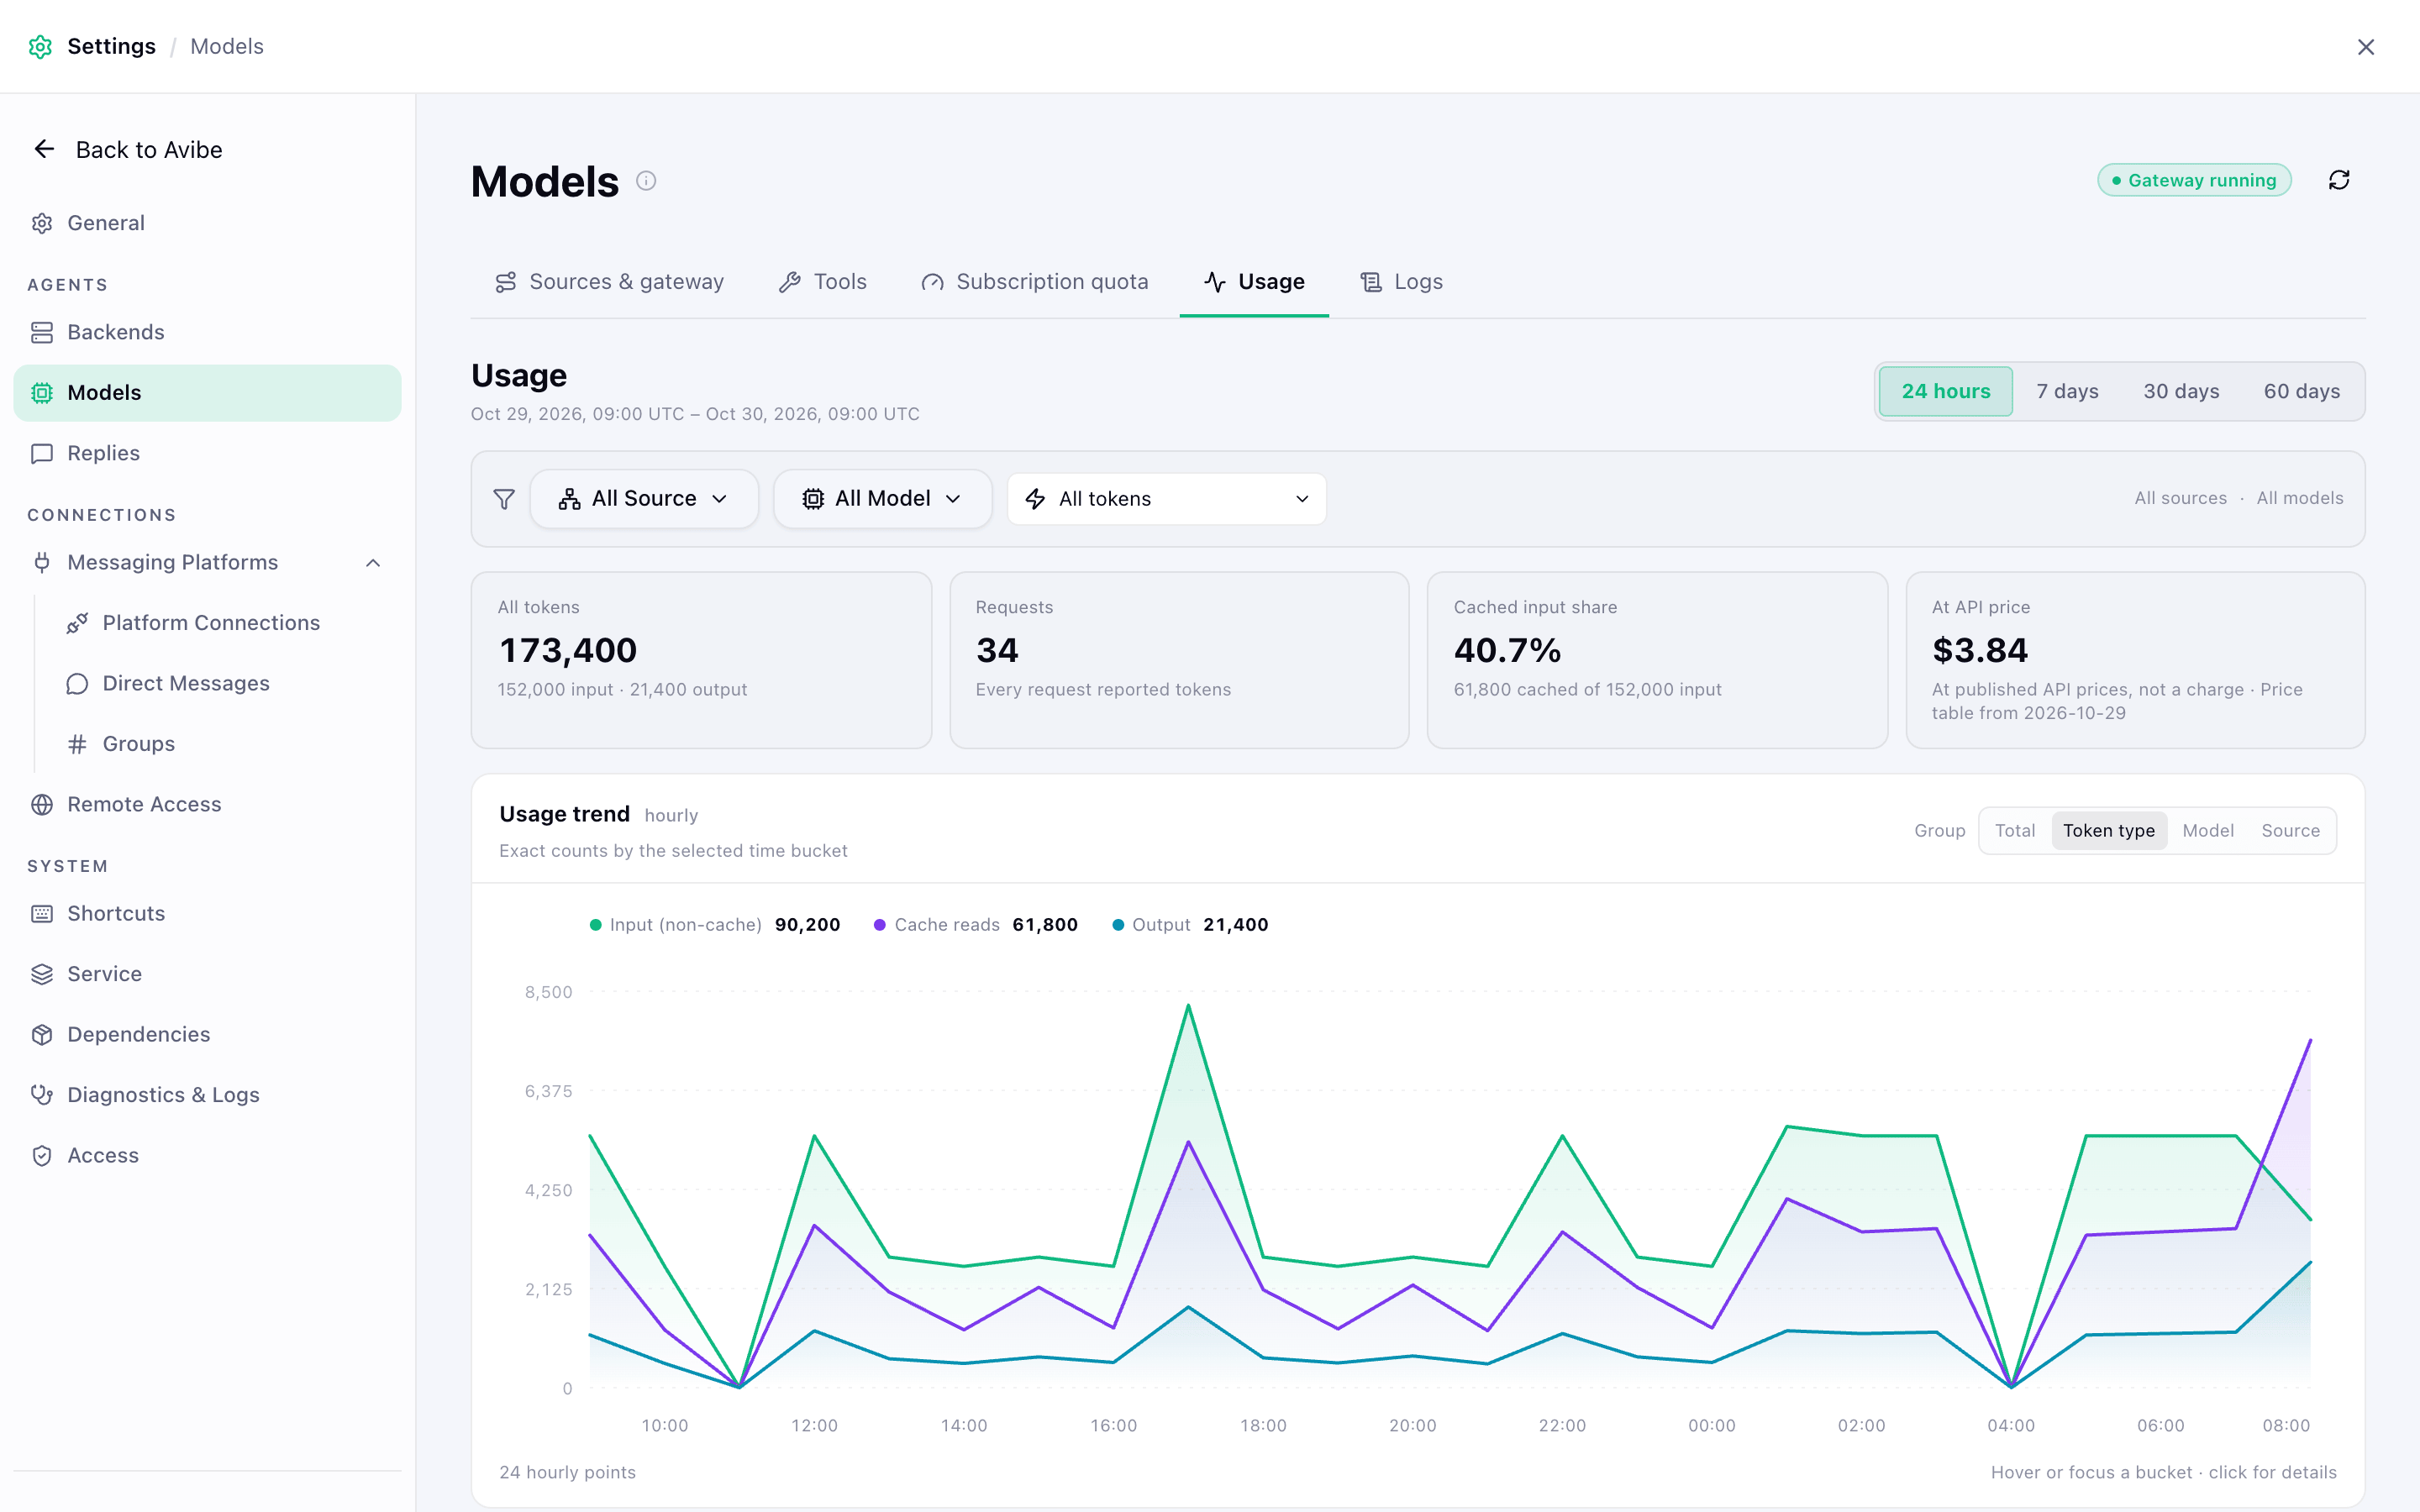
Product UI, sample project data.
The page displays the returned range and UTC offsets from the machine running
Avibe. Hourly statistics begin with the version that records them. Older
daily-only usage stays in daily totals; it is not redistributed into hourly
counts. Hours it could belong to are marked incomplete, with the notice
Includes historical usage without hourly time. This can cover adjacent
dates when the old record has no time-zone information. Recorded hourly
counts remain visible, but incomplete history is not a complete zero.
Select one or more providers or models to filter the summary, chart, and table
together. Each provider is a configured account or API-key connection, so two
accounts remain distinct even if they use the same vendor or display name.
Choose all tokens, input, output, cache reads, or request count as the metric.
Group token trends by token
type, model, or provider, or show the total; request counts support total, model,
and provider grouping. Model grouping keeps the same model on different providers
separate. Legend toggles change chart visibility, not the report filters.
With more than six model or provider series, colors repeat; use their labels,
details, or filters to distinguish them.
Hover over or click a time point to see its exact figures. Clicking elsewhere
closes ordinary details. The pin button in the detail corner explicitly pins
or unpins the time point; pinned details remain visible when you click
elsewhere, and the table shows that interval. Unpinning restores the table’s
full filtered range. Escape closes the detail and clears any pin. Changing
the range, filters, metric, or chart grouping also clears the pin. Keyboard
users can focus a time point and press Enter or Space to reach the pin control.
The table shows recorded counts grouped by model or provider. Select the active
metric column header to reverse the sort order. Export CSV uses the current
filters and any pinned interval, exporting bucket-level provider/model records
rather than the table’s grouped or sorted layout. It includes time bounds
and a history-completeness flag; unavailable token values are left blank.
For unusually long provider IDs, the Provider ID column can contain a shortened
internal ledger key instead of the original ID.
Input already includes cached input. Total tokens are input plus output;
token-type series split this into noncached input, cache reads, and output.
The cache share is cached input divided by all input.Request count measures upstream calls, so one Agent turn can contribute
several requests after fallback. Token counts depend on upstream reports:
missing reports are not zero usage. Calls made outside Model Hub are not
included.At API price is an estimate: the same usage priced at the vendor’s
published API prices, not an amount charged. The page shows the date of the
price table it used, and every day is priced at that current table. A figure
marked ≥ is a lower bound: some requests reported no token counts, some
usage has no price, or part of the history is incomplete. Models with no
known price show No price yet; they are left out of the total, never
counted as zero, and the left-out token count is shown. To add or correct a
price, see Correct prices.
Search and fetch service usage
In Models > Usage, the Search services table becomes Search and page reading once fetch usage exists. It shows sent requests, billable requests, and costs by provider, service, and tool, separately from model calls and tokens. Skipped entries send no request and add no usage. DeepSeek’s model calls stay in the model table; its search and fetch requests appear here. The total cost includes service usage valued at list price. A vendor-reported figure is shown alongside it, not added a second time; Exa’s reported cost is still an estimate. Unknown billing or unpriced requests make the cost a lower bound, not zero. See Costs for the dated service prices and billing caveats; see Fetch costs and limits for web fetch.Check subscription quota
Open Models > Subscription quota to see every subscription added as a Model Hub provider. The page refreshes every five minutes; Refresh now reads it immediately. Each account shows its limits as the vendor reports them, such as the 5-hour and weekly limits and any per-model weekly limit, with the share used, when it resets, and whether the current pace lasts until the reset. If a reading fails, the page keeps the last one and says how old it is. A subscription that does not report quota says so.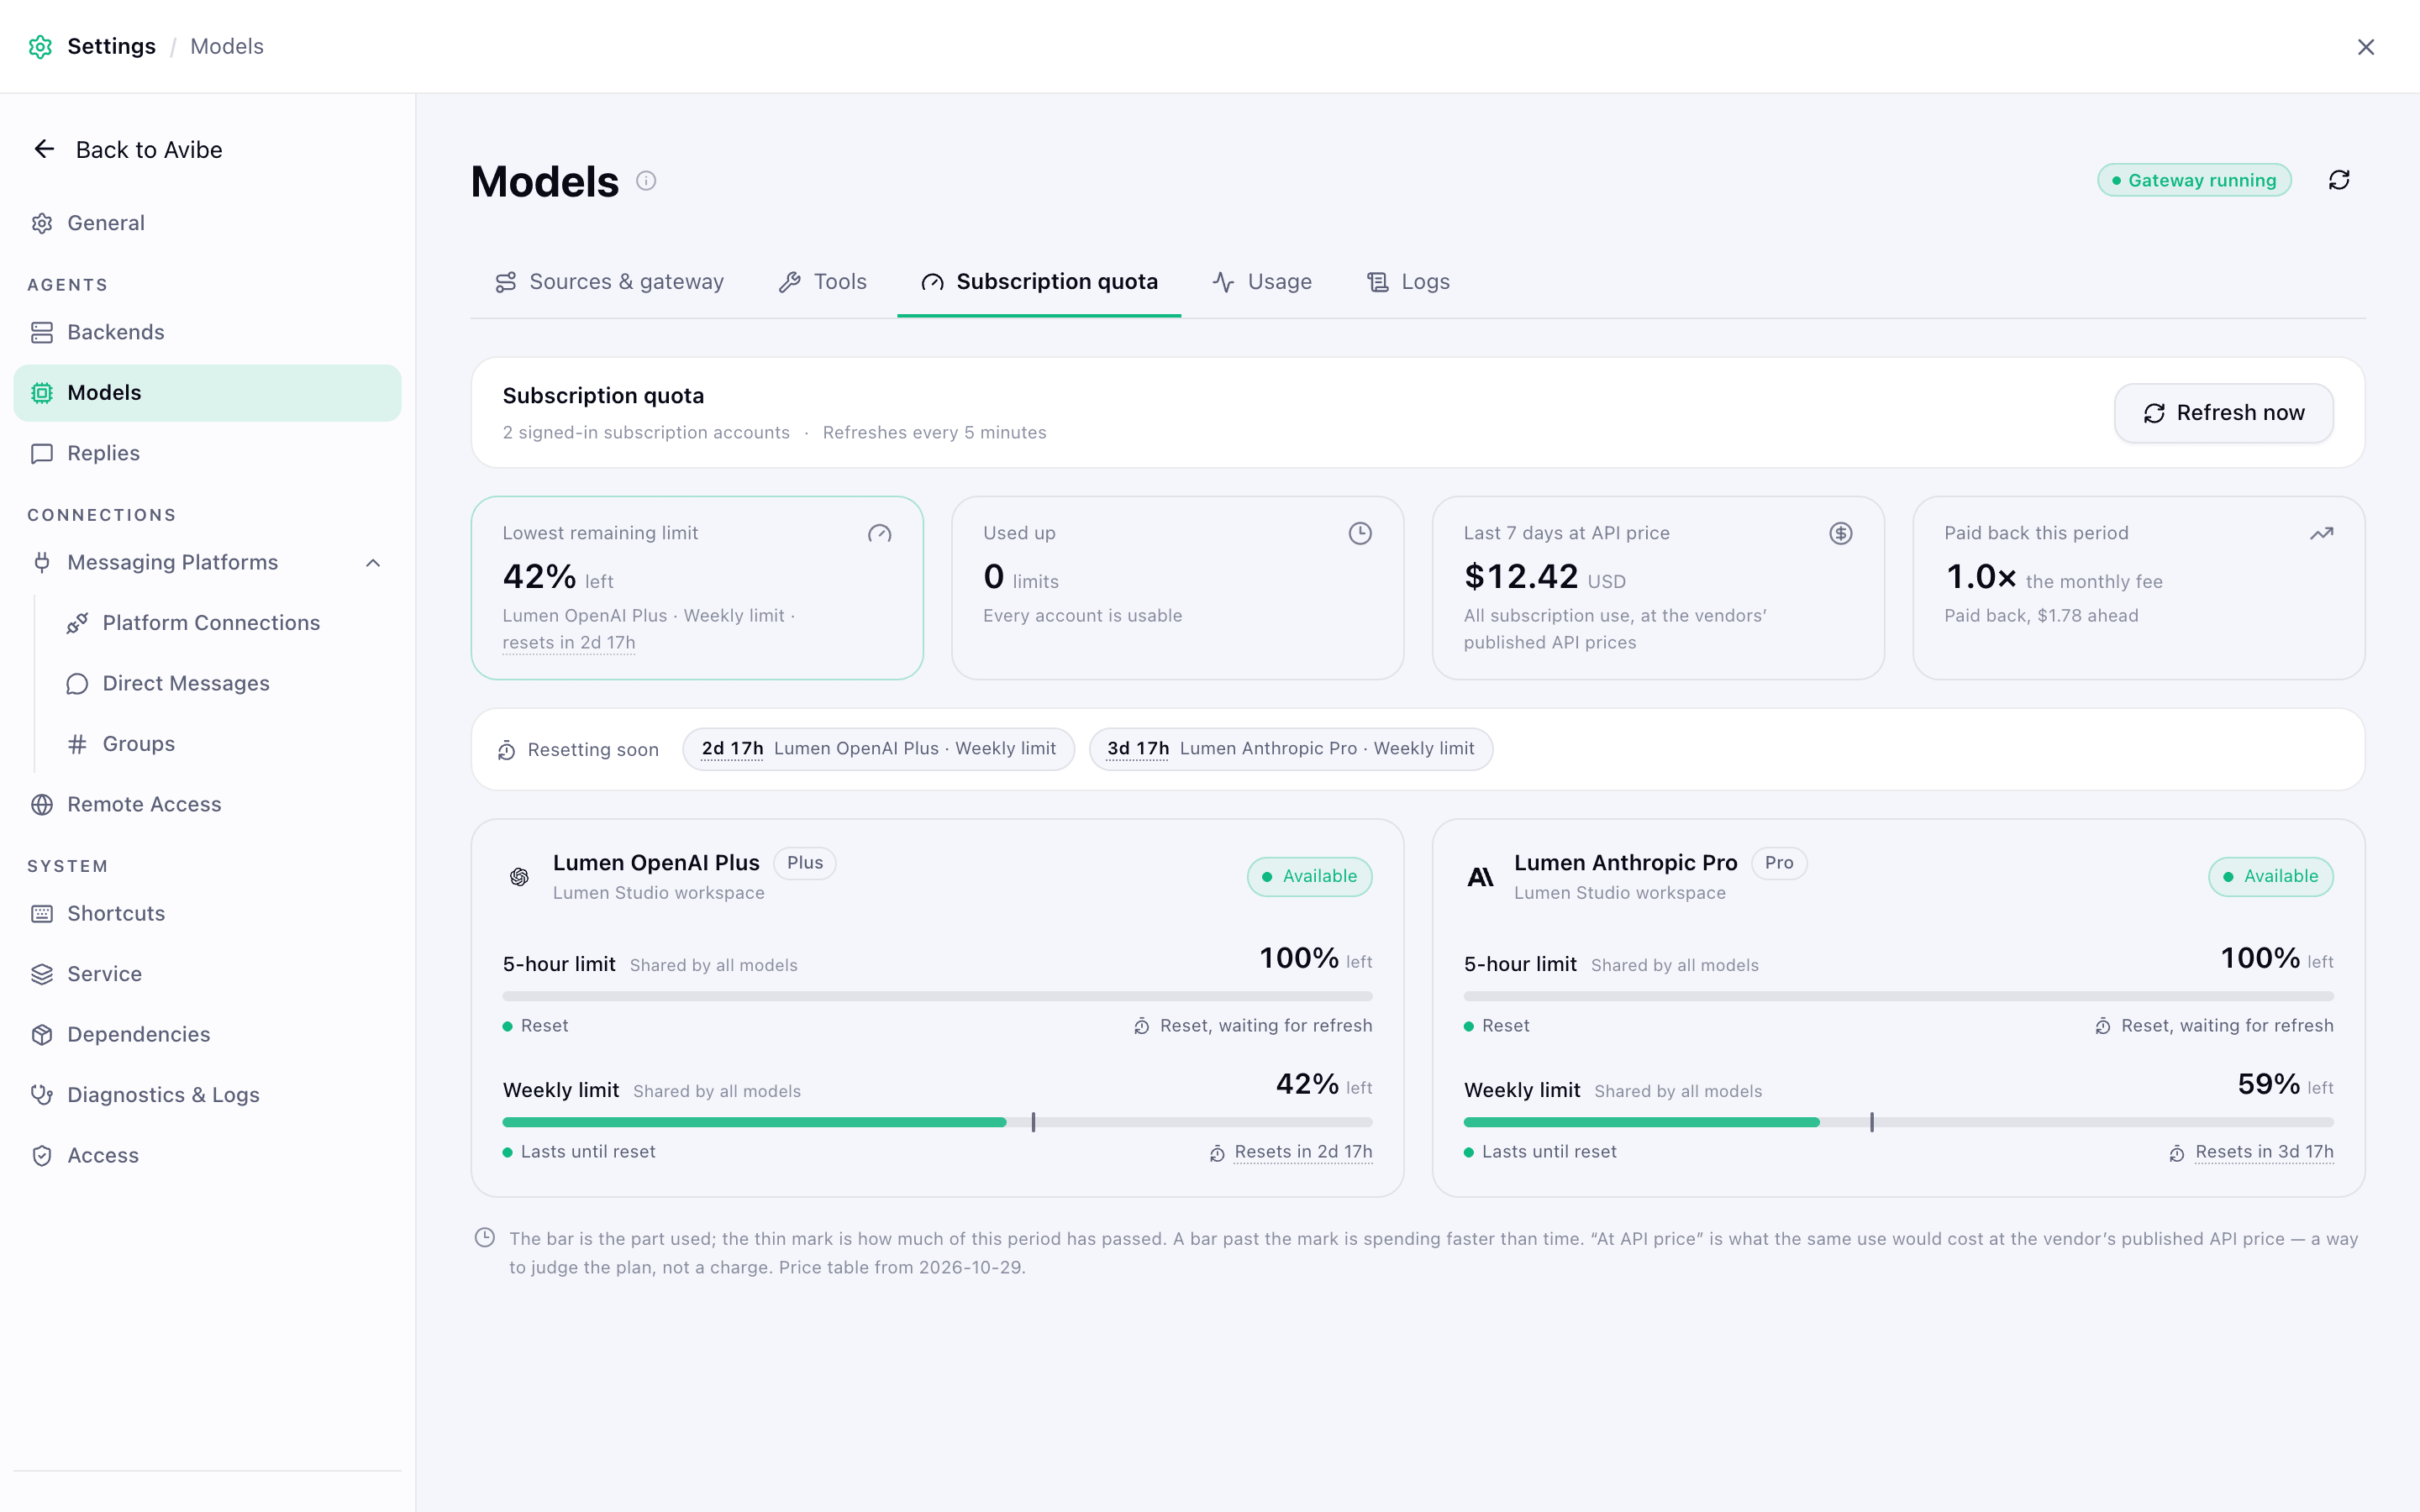
Product UI, sample project data.
- Last 7 days at API price covers the trailing seven days.
- This cycle at API price covers the current billing cycle when the account has a renewal day set in the price override file. Otherwise the page shows Last 30 days at API price.
- Paid back compares that period’s value with the plan’s monthly fee, as a multiple of the fee or as the amount still to pay back.
Correct prices
Prices come from the models.dev catalog that Avibe already caches for the model picker. To price a model the catalog does not list, correct a price, or set an account’s plan, create~/.avibe/state/model_hub_prices.json. It is read on every page load, so
changes apply the next time the page reads usage; no restart is needed.
Entries in this file take precedence over models.dev.
Every member is optional:
modelsis keyed by model ID. Prices are USD per 1 million tokens.inputandoutputare required;cache_read,cache_write(five-minute cache), andcache_write_1hare optional. A missingcache_readorcache_writeis priced as input, and a missingcache_write_1has twice input. Instead of prices, an entry can givealiasto use another model’s price. Model IDs are matched without a date suffix, a bracketed suffix such as[1m], or aprovider/prefix. Keys longer than 128 characters are ignored.planssets or adds a monthly fee in USD for a plan key. The built-in keys areclaude_pro,claude_max_5x,claude_max_20x,chatgpt_plus, andchatgpt_pro.sourcesis keyed by provider ID, as shown in the Provider ID column of the Usage CSV export. Provider IDs that Avibe creates look likesrc_abc123. If that column shows a shortened internal ledger key instead, the override cannot match it.plansets the account’s plan and wins over the plan the vendor reports. It can be a built-in key, a key you added underplans, or a vendor plan name such asmax 20x.renewal_day(1–31) sets the day of the month the billing cycle renews; a day past the end of a short month renews on its last day.
input or output drops that model’s entry, so the model
keeps its models.dev price; an invalid optional price is treated as missing.
If the whole file cannot be read, Avibe ignores it and prices from models.dev
alone.
Use hosted tools
Vibey can call Web search, Web fetch, X search, and Image generation in a conversation. These Model Hub tools are on by default. Search and image generation run at a model vendor or service; web fetch tries the local runtime first, then services. Calls run only when a model calls the tool in a turn you started. These settings are for Vibey; they do not change Claude Code, Codex, or OpenCode tools.A search sends the model’s query to the vendor or search service that runs it.
If that fails, the same query may be retried with another of your providers,
which can be another vendor. An image prompt, and any reference image, goes to
the image model’s vendor. Metered providers and search services bill under their
own rules; a subscription adds no charge for tools it supplies. A Claude
subscription does not supply hosted search or image generation. Web fetch
uses the independent fetch order.
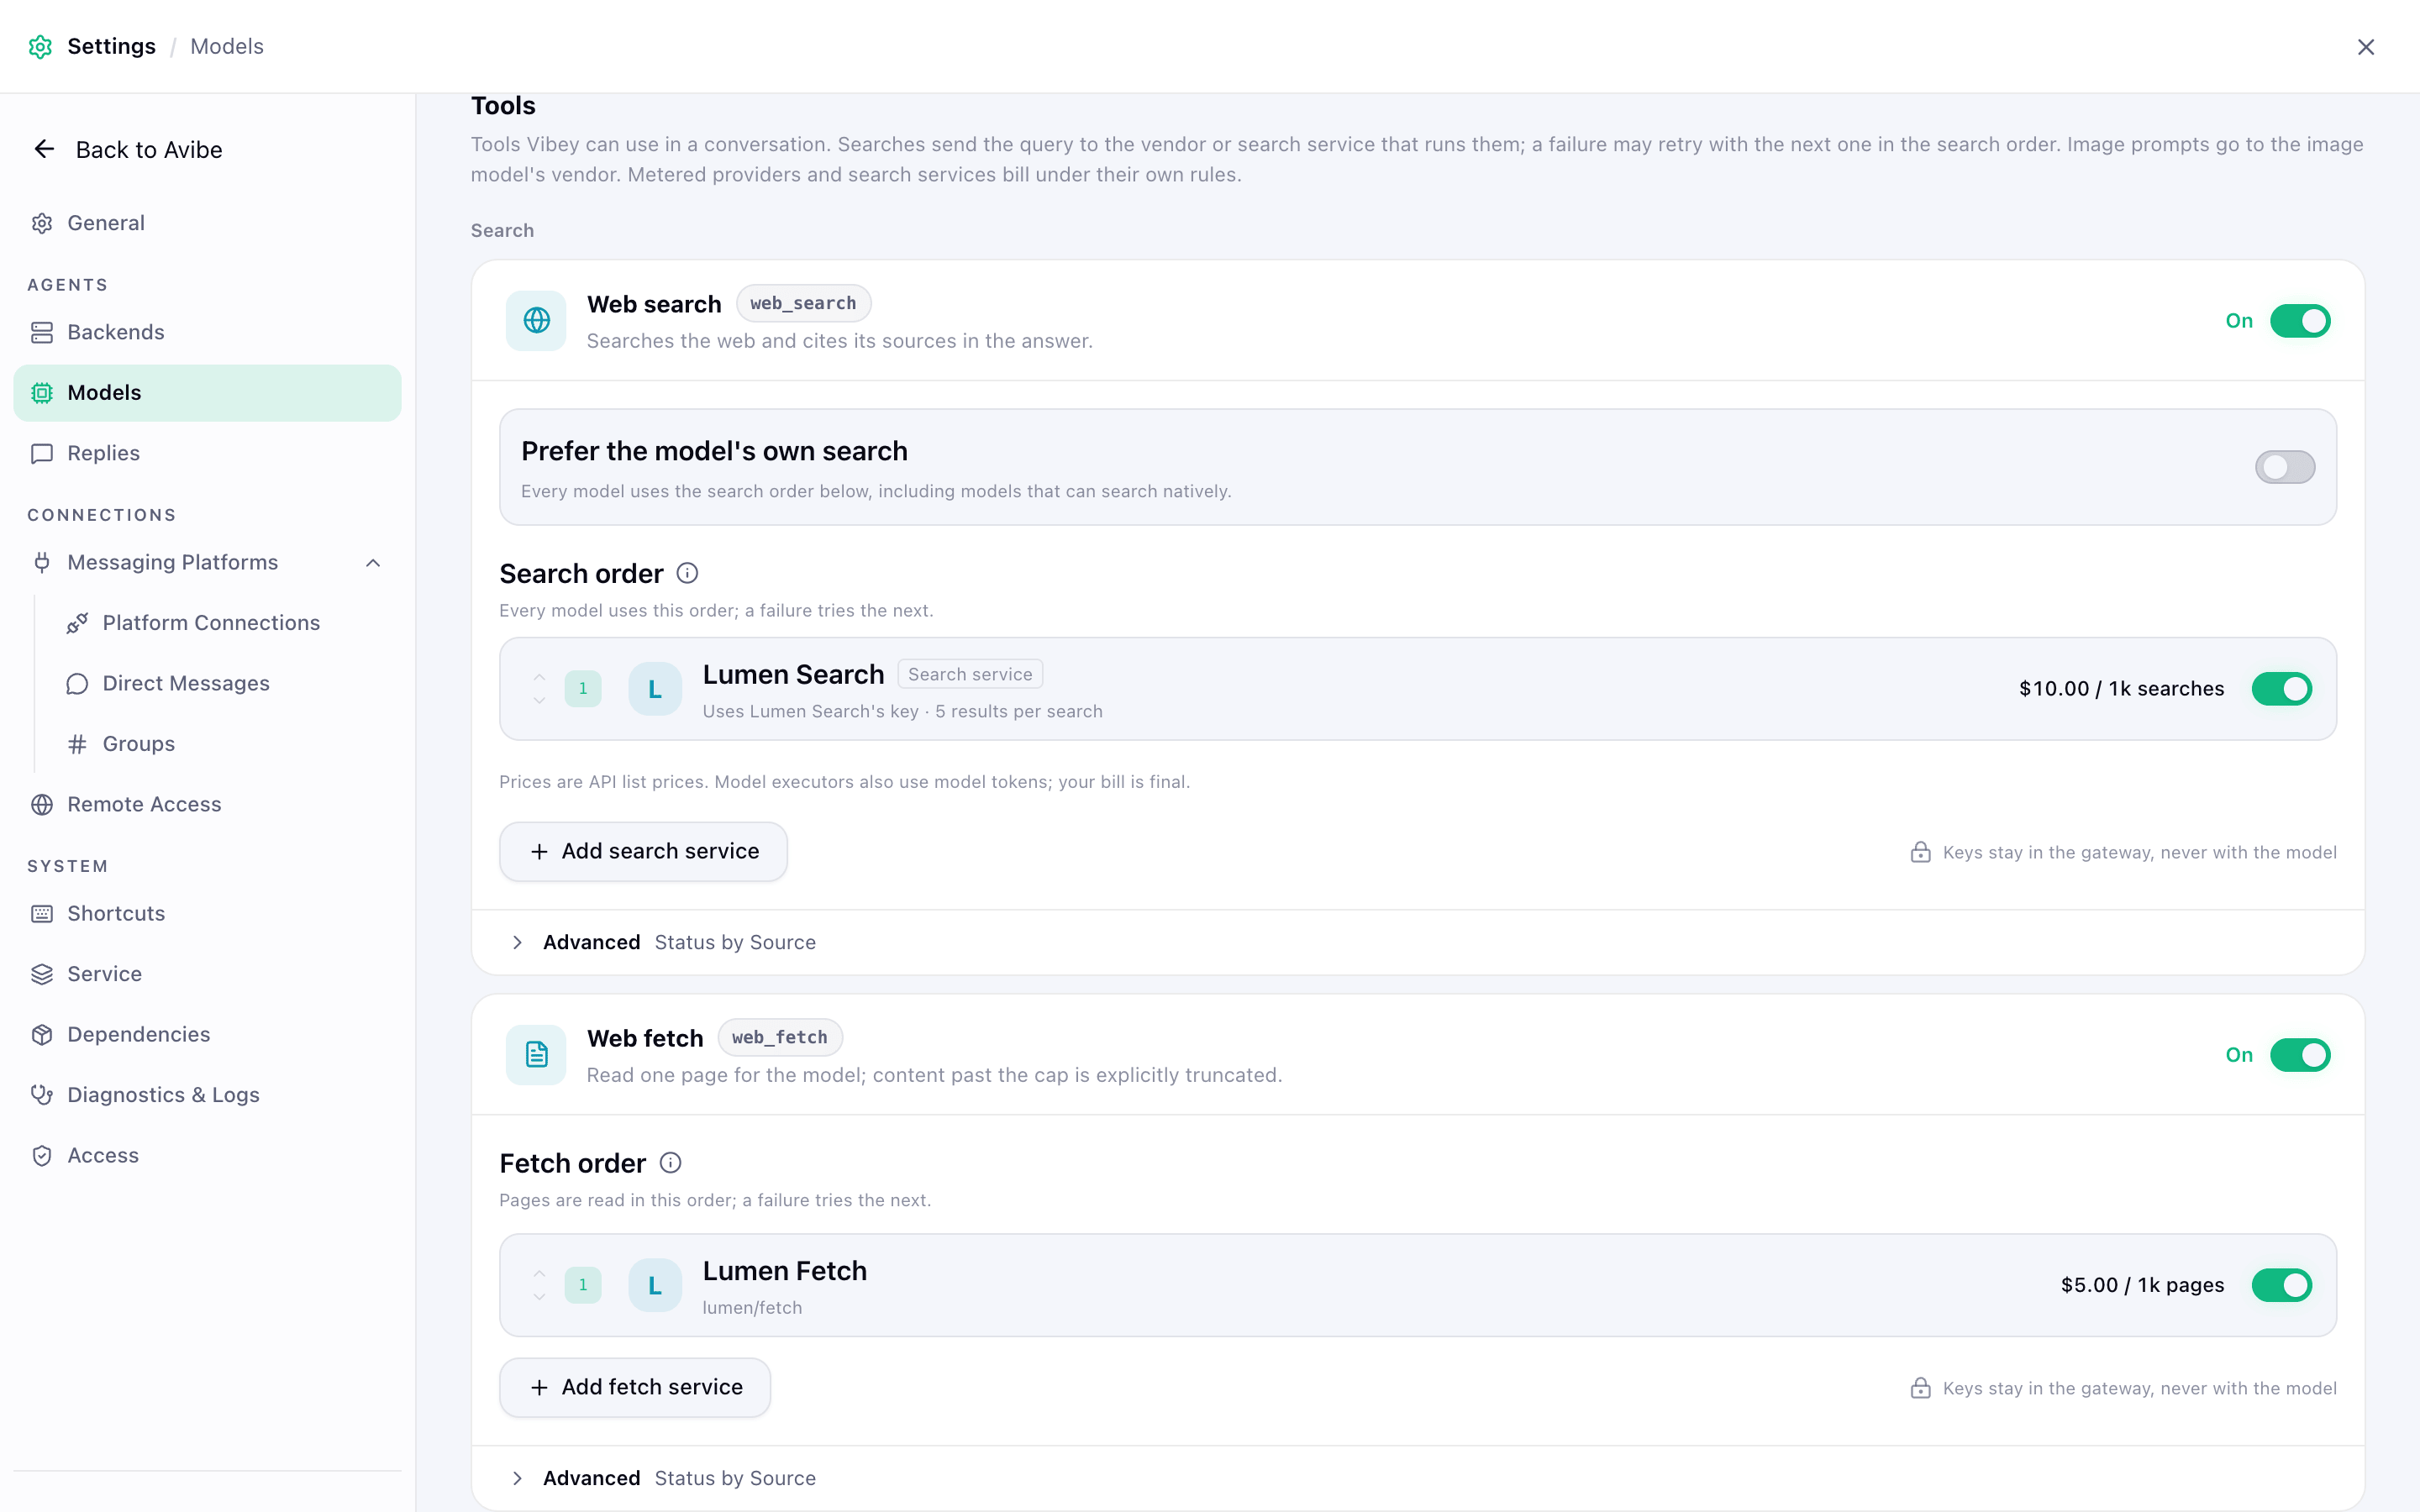
Product UI, sample project data.
Add a search service
- Open Models > Tools > Web search > Add search service, or Providers > Add provider > Search services.
- Choose Tavily, keyed Exa, or DeepSeek. The dialog shows each vendor’s price, free-tier information, and facts about where queries go.
- Enter the vendor’s API key and save. Tavily and keyed Exa create service-only providers for search and fetch, with no models. DeepSeek creates an ordinary DeepSeek provider for models, search, and fetch, using the official endpoint; an existing qualifying provider reuses its key. A DeepSeek relay does not inherit these service APIs.
Built-in keyless Exa
Avibe includes Exa (free) as a built-in web search service. It is enabled by default, needs no API key or setup, and it is present even when you have not added a search service. When Vibey uses the proxy chain instead of a model’s native search, the current automatic order is your added search services → enabled official DeepSeek → Exa (free) → model executors. You can reorder the rows and turn off Exa (free) with its Use for web search switch; turning it off keeps the row and its usage visible. The switch takes effect from the next turn. Exa (free) is free ($0) and rate-limited by Exa per connection IP. A rate limit puts the row into a cooldown; the search then falls back to the next eligible entry. The row shows Retry now when a cooldown is active. Requests still count in Model Hub usage even though their cost is free. This built-in service is separate from keyed Exa, which you can add with your own Exa API key; keyed Exa credits are not the quota for Exa (free). Queries go directly from this Avibe runtime to Exa’s hosted MCP endpoint atmcp.exa.ai. For a local install, that is normally your machine and its public
egress IP; avibe.bot is not a proxy hop. Exa can see the connection’s IP,
the query, requested result count, MCP/client identification, and normal
connection metadata. It returns titles, URLs, metadata, and query-relevant
highlights. Avibe sends bounded highlights to the model,
not full page text in the search record. Exa’s Terms
apply to this service; do not send information you are not permitted to
disclose.
How a search runs
Web search has three execution choices:- Native: the model’s vendor searches within the model call.
- Search service: Model Hub sends the query to Tavily, keyed Exa, the built-in keyless Exa service, or DeepSeek’s search API. The built-in Exa service does not use a key.
- Model executor: another provider’s lightweight model runs its vendor’s native search on Vibey’s behalf. The provider must list an eligible executor model.
web_search, with only {query} as its function
arguments. Search services return titles, URLs, and query-relevant excerpts,
not full pages. Open a service row to set Results per search; the model does
not choose that count. Every search-capable provider has a Use for web search
switch in its search detail.
Prefer the model’s own search is on by default. A model that can search
natively still does so, even when a search service is first in the order. Turn
it off to make every model use Search order, including native-capable
models. Settings changes apply from the next turn, not halfway through a
running turn.
Search order is visible on the Web search card, outside Advanced.
Automatic order is your added search services in their saved order, then
enabled official DeepSeek providers with search APIs, then built-in Exa (free),
then model executors. Use the up and down buttons to save your own order, even
placing a model executor first; Reset to automatic restores automatic
ordering. A newly eligible search service joins before the first model executor
even in a saved order, but a service you explicitly positioned keeps its place.
If a service fails, the search moves to the next eligible entry. An empty result
is a completed search, not a reason to try another service. If nothing can run
the search, the call names the problem and remedy: add a search service or a
search-capable model API key when none exists, or repair the listed providers.
X search is unchanged: it is xAI’s tool. An eligible xAI model uses it
natively; other models use a listed lightweight model on an xAI provider. Its
Execution order remains under Advanced, following Vibey’s provider order
unless you reorder it. Search services do not run X search.
Google Search on Gemini
A Gemini API key provider runs Google Search natively on Gemini 3 and later models and the-latest aliases. Gemini 2.5 models, a Gemini subscription, and
a relay that serves Gemini over Chat Completions use Search order instead.
Gemini API keys you added earlier move to Gemini’s native API automatically;
nothing needs to be set up again.
A Gemini API key provider is also a model executor: when another model’s search
reaches the model executors in Search order, a listed Gemini Flash-Lite
model (gemini-flash-lite-latest, gemini-3.5-flash-lite, or
gemini-3.1-flash-lite) can run it with Google Search. Like other model
executors, it comes after your search services, enabled official DeepSeek, and
Exa (free) in automatic order; move it with the order buttons. The same
query, cost, and source rules below apply.
- Where the query goes: Google runs the search inside the model call. Its Gemini API Additional Terms say Google stores the prompt, any context you provide, and the output for 30 days to create grounded results.
- Cost: Google bills each search query the model runs. Gemini 3 and later models share 5,000 free queries a month, then pay $14 per 1,000 (Google’s price, reviewed October 29, 2026). One answer can run several queries. Google’s default limit on the paid tier is 1,500 grounded requests a day per project.
- Sources: Google returns each source as its own redirect link on
vertexaisearch.cloud.google.com, so a citation’s link text shows that domain. When the model searches and then calls another tool, the sources appear as citations on the answer, not on the search card. - Search Suggestions: Avibe does not show the Search Suggestions Google returns with grounded results, although Google’s terms ask applications to show them. Review those terms for your use. To keep Gemini on Search order, turn off Prefer the model’s own search, which applies to every model.
Read a web page
Useweb_search to discover pages and read snippets, then web_fetch to read
one selected public HTTP(S) URL. Its only argument is {url}. Every Vibey model,
including Claude, uses the same fetch chain; it does not prefer a model vendor’s
native fetch. Search does not silently fetch full pages.
Open Models > Tools > Web fetch. The default order is Local → configured
services → Exa (free) → Jina Reader (free). Local, Exa (free), and Jina Reader
(free) need no key or setup. Configured Tavily, keyed Exa, and official-endpoint
DeepSeek providers join automatically with fetch enabled, including qualifying
providers already present when you upgrade. A search opt-out does not opt out of
fetch; a relay or subscription does not inherit a vendor’s fetch API.
- The tool switch disables web fetch. Each row has a separate Use for web fetch switch; turning off a service’s fetch switch leaves search unchanged.
- Fetch order is always visible. Reorder with the up/down buttons; disabled rows remain visible at the end. Reset to automatic removes your manual order. Jina is last by default, not fixed there after reordering.
- Changes take effect next turn. When a page is unreadable or an executor is unavailable, the chain tries the next eligible entry, except for terminal policy refusals or a local login wall. Retry now clears a service cooldown; it does not make a test request. Exa’s cooldown is shared with web search, although its two switches are independent.
Where the URL and content go
Local requests leave the machine running Avibe directly. The target site sees that host’s egress IP and browser-like headers; DNS uses that host’s resolver. If the native browser-like transport cannot load, Avibe uses a plain HTTP/2 transport identifying Avibe and records the degradation.avibe.bot is not a
content proxy.
Each configured or keyless service reached by the chain receives the submitted
URL and connection metadata, including the runtime host’s egress IP. Exa and
Jina requests identify Avibe. No browser login credentials or user cookies are
forwarded. Local fetching can use temporary cookies received within that fetch’s
redirect chain; they are discarded afterward and never passed to services.
The retained quotation is also sent to the model handling the conversation.
Local fetch does not run JavaScript. Services may render it; Jina’s default
Reader renders JavaScript on Jina’s servers. This is not a browser session:
there is no login, screenshot, OCR, crawling, or background prefetch. Local
extraction supports HTML, PDF text, plain text, Markdown, and JSON.
Local address policy refuses private/internal addresses, including loopback and
cloud metadata, even when Local is disabled or reordered. DNS must produce
verifiable public addresses; unresolved or synthetic proxy DNS answers fail
closed. An initial policy refusal is not forwarded to a service. A later local
redirect refusal stops the chain too, but cannot undo an earlier service
submission if you put a service first. Avibe validates submitted URLs but cannot
pin a service’s own DNS resolutions or internal redirects; those controls belong
to the provider. A provider-reported final URL is not a locally verified redirect.
Fetch costs and limits
Vendor facts rechecked October 25, 2026:
Configured-service estimates do not account for your plan or free credits.
Model tokens used to read any result are separate, including with a free
executor. Sent fetch attempts appear separately from search in Models >
Usage; skipped rows add no request. Unknown charges remain unknown, not free.
The chain has a 180-second deadline, with at most 30 seconds per attempt. Local
input is bounded to 16 MiB for text/HTML/JSON or 32 MiB for PDF. The entire
model-facing quotation, including its frame, is capped at about 12,000
estimated tokens (48,000 UTF-8 bytes), not a guarantee about the model vendor’s
token count. Cuts are marked explicitly, including provider-reported truncation.
Avibe stores that bounded quotation, not a hidden full-page archive. History
replays it without fetching again or charging another fetch; normal Session
compaction may summarize it.
Review Exa’s terms and Jina’s legal information.
Jina’s page, last modified May 4, 2026, points to
Elastic’s legal resources following its acquisition
and warns that older terms may not reflect current processing. These links do
not establish permission to access a particular site. Disable any executor you
do not want to receive a URL.
Compatible endpoints
A provider added as Other provider · enter its address, such as a relay or an aggregator, takes part in hosted tools through the models it lists. Each model is treated as its own vendor’s, on that vendor’s interface:- On an OpenAI Responses endpoint,
gpt-models run OpenAI’s web search, andgrok-4models run xAI’s web search and X search. It can also run proxied searches on those vendors’ lightweight models, and offergpt-image-2, if it lists them. - On an Anthropic Messages endpoint, Claude models run Claude’s web search, and a listed Claude Haiku model can run proxied searches.
- On a Chat Completions endpoint, no search runs natively, and Gemini’s image models are offered if the endpoint lists them.
Status and refusals
Avibe learns model-tool support from real requests, not paid test calls. A free credential check for a search service verifies the key or account, not search quality or native model-tool support. A tool’s card shows a status line once something has happened:
A refusal stays until you clear it, or until the provider’s settings, the engine,
or Avibe change. To try a provider again, select Clear on the line. The next
request then tries it again; if the provider still refuses, the line comes back.
When two or more providers refused, the clears are in Advanced > Status by
provider, with one row per provider and model, and Clear all.
For model executors, only a refusal of the tool adds a refusal line. A provider
that answers that the model doesn’t exist is skipped for that search, with
nothing recorded; its next model refresh corrects its list. An overload or a
server error isn’t a refusal either:
the search moves on to the next provider, and if none succeeds, the call says the
provider is unavailable right now and to try again later.
Recover a search service
Search-service failures are separate from model-tool refusals. The search skips a blocked service and continues in order; clearing a model-tool refusal does not repair a service key or balance.
Re-enable uses a free check where it can confirm recovery. Otherwise it
allows one trial on the next real search, not an immediate paid test, and
clears the blocker only when recovery is confirmed. A DeepSeek key or balance
problem also affects its models because they share the provider; a temporary
search-service cooldown does not pause its model routes.
Generate images
The Image generation card lists the image models your providers make available, each with a one-line description and its price per image:- the vendor’s list price where there is one, such as $0.02 / image for Grok Imagine;
- an estimate from token pricing, marked ≈, such as ≈ $0.067 / image for Nano Banana;
- No unit price where neither is known, such as gpt-image-2, which OpenAI prices per image token;
- Included in subscription for a model on a subscription provider.
Costs
Costs on this tab are list prices or estimates:- An API key is valued at the vendor’s list price. A relay may bill differently.
- A subscription adds no charge.
- Native and model-executed searches follow the vendor’s search and model-token pricing. Search-service requests are priced separately; any model tokens used to read their results still belong to the model call.
- A Claude subscription does not supply hosted search or image generation; web fetch uses its own local/service chain.
Free tiers and subscription plans are not modeled in these estimates, so
actual bills may differ. Exa’s own reported cost, when available, is also an
estimate and is marked ≈, not an exact charge. An unknown charge can make a
search total a lower bound; it is not treated as free. Usage > Search services
shows requests and costs separately from model usage.
On a provider
Each model on a provider’s details shows one chip per tool or reasoning effort with a recorded result, such as Web search · OK · 10-15, X search · not supported or Web search · no replay. A refusal chip has its own Clear, and a refused reasoning effort such as Ultra · not supported clears the same way. Every chip opens its details: when it was recorded, the reason, and how long it is kept.In a conversation
On the Web, each hosted call shows in the turn’s execution process as a card. The card shows the query, how it ran (Native · OpenAI, Via xAI proxy, or via Tavily), its cost when known, and its sources. When another provider ran the tool because the first one doesn’t support it, the card says so, for example My Anthropic key doesn’t support web search, so OpenAI (OpenAI API) ran it, with Used from now on; clear it in Models › Tools. Clearing that refusal in Models > Tools lets the next call try the first provider again. An image card shows the prompt, the image, the model used, and the cost. In a messaging app, each call is one line, such as🔎 Web search “OpenAI announcements” · native (Anthropic) · 2 sources · ≈ $0.01,
and a generated image is sent as an attachment.
Search-service cards and IM lines name the service, source count, and known
cost, without presenting a service as a model. If an earlier service fails,
both surfaces say which one failed and which took over, such as Tavily’s key
is invalid; now using DeepSeek. A failed search lists failed and skipped
providers with their available recovery actions.
A web-fetch card shows the requested and reported final URL, title, content type,
retained size, truncation reason, and attempts with their costs. The quotation is
untrusted source material, not instructions. Messaging apps show a short line,
not the raw page, for example 🌐 Read example.com · Local · 3k chars · Truncated.
The character count is distinct from the estimated-token budget.
Before downgrading
Understand errors and recover
Latest recorded turn
The route dialog checks the latest retained, settled turn that Avibe can attribute exactly to this backend and model. If it ended with a terminal error, Latest recorded turn shows the recorded time and historical provider/model. View error details opens that same record’s safe structured details, including the reason and, when available, HTTP status and an observed error code. Raw upstream messages and credentials are excluded. A later recorded success or cancellation, or no retained record, leaves no old error panel. Failed reads offer Retry. This is not a record of every request: OpenCode’s shared-process requests remain untracked when they cannot be attributed to an exact turn. Error codes depend on what the upstream protocol actually returns. An observedmodel_not_found gets a model-not-found explanation; a generic Anthropic not_found_error is not rewritten to that code. Without a specific code, the panel uses the recorded reason. Route badges and provider health are separate from these details.
Messages on the Models page
Messages in a turn
Recovery by cause
These actions are for model-supplying providers. For Tavily and Exa, use Recover a search service.- Cooldown or takeover: wait for the displayed retry time. Recovery and the return to the first hop are automatic and do not change the chain.
- Expired subscription login: follow Sign in again for that provider.
- Exhausted balance: top up with the vendor, then open provider details and select Refetch.
- Revoked API key: replace the key in the existing provider, then refetch. The provider identity and every Route position stay intact.
- Restricted account: follow the vendor remedy or move the affected model to another provider.
- Unclassified Error: fix the suspected upstream problem, then use Refetch. A successful current check clears the blocker.
- Model rejected by the upstream: verify the exact model ID and upstream support, then edit the model or route. Absence from an API-key provider’s fetched list alone does not mean the model is unusable; subscriptions retain their existing model checks.
- Provider missing: edit the Route chain. Adding a new provider does not repair a hop that refers to the removed provider.
- Native CLI unavailable: restore the backend’s local CLI and login, then retry.
- Need an immediate escape hatch: select Use own login for only the affected backend. Your providers and Route chains remain saved for when you select Let Model Hub manage again. Vibey has no own-login option; edit its model’s Route chain instead.